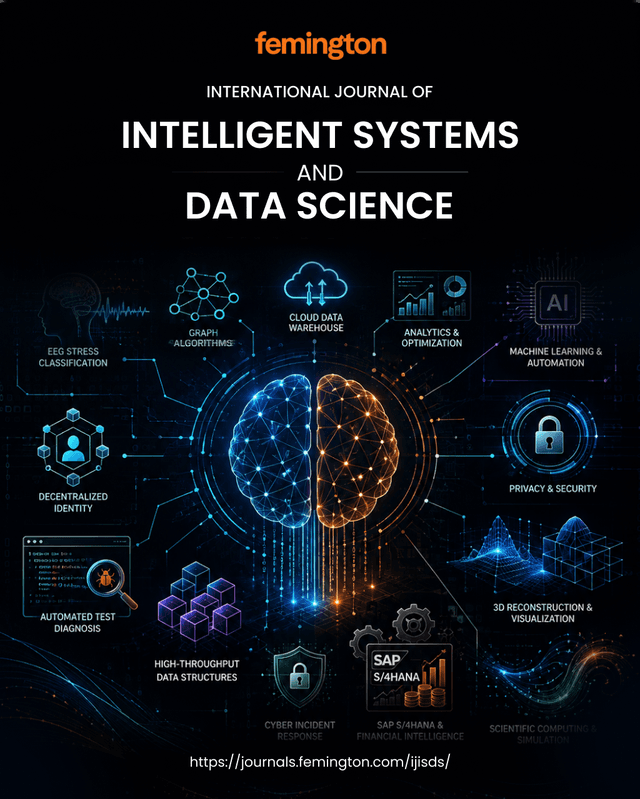
This issue brings together a broad range of research spanning artificial intelligence, machine learning, cybersecurity, enterprise systems, data engineering, blockchain, computer graphics, software testing, and computational science. The featured studies explore interpretable EEG-based stress classification, privacy-preserving machine learning, intelligent cyber incident response, SAP S/4HANA automation, anomaly detection, graph algorithms, sentiment analysis, decentralized identity, and advanced visualization and simulation techniques. Collectively, these contributions demonstrate how emerging computational methods can address complex challenges in intelligent systems, secure data management, enterprise decision-making, scientific computing, and the development of robust, scalable, and trustworthy digital technologies.
Published
August 2026
Contributions
20 articles
Access
Open access
Explore the research published in this issue of ijisds.
Monisha Rengaraj
This paper formulates key-item placement in adventure-style games as a reachability problem on directed graphs with rule-constrained edges, introducing formal algorithms that support progression feasibility while enabling controlled randomness. Three placement procedures are defined in this paper: Random Fill, Forward Fill, and Assumed Fill, with Algorithm 1 providing the formal specification of Random Fill; forward and assumed fill are described in prose, with their algorithmic structure outlined. Generalized search routines (including sphere-based progression and a heuristic playthrough simulation) compute accessible regions and derive guidance for item ordering. A world-generation framework and a path-aware complexity score are provided, together with an evaluation suite that quantifies failure rate, runtime, bias orientation, and a composite ''interestingness'' measure decomposed into fun, challenge, satisfyingness, and boredom. Extensive stochastic evaluation on synthetic graphs characterizes algorithmic trade-offs, showing how assumed-knowledge placement improves completeness at higher computational cost while forward expansion scales efficiently with world structure. The study yields prescriptive insights for selecting placement and search strategies by target world topology and desired player experience, offering pseudocode and metrics to support content-generation pipelines in computational game design.
Monisha Rengaraj
This paper proposes TrustScale ML: a verifiable and privacy-preserving framework for distributed ML to detect computing integrity, protect the confidentiality of gradients and enable scalable collaborative learning. We propose TrustScale ML, a scalable ML system integrating PoL, which enables the efficient verification of local ML computations, utilizing the CKKS homomorphic encryption scheme for the protection of gradients during distributed model training. The framework supports a variety of distributed learning settings, including data and model parallelism, centralized and decentralized optimization, and synchronous and asynchronous training. To improve trustworthy, security mechanisms should aim at integrity of the model, verification of computation, and protection against unauthorized access to sensitive learning information. The research describes the overall system architecture, communication and security protocols, verification workflow, and implementation methodology. Further, it provides a systematic evaluation agenda for evaluating correctness, robustness, privacy, computational overhead, and scalability across representative ML workloads. TrustScale ML provides a unified framework for trustworthy distributed learning systems through verifiable computation and privacy-preserving gradient processing. The suggested framework is aimed at guiding future empirical studies and practical application of secure, scalable and verifiable distributed ML systems in heterogeneous and possibly untrusted computing environments.
Apeksha Bhuekar
This paper presents a weighted multi-model ensemble approach for discerning sentiment polarity in text documents, specifically consumer reviews. We address the binary classification problem of identifying positive versus negative sentiment by proposing a hybrid framework that integrates generative, discriminative, and deep embedding-based models. Our key contribution is a weighted voting mechanism that leverages cross-validation to assign model-specific weights, effectively harnessing the complementary strengths of its diverse constituents. This ensemble strategy is evaluated on widely recognized movie review datasets, where it demonstrates robust performance compared to standalone models. Our method achieves 93.1% accuracy on the IMDB dataset and 90.6% accuracy on the Rotten Tomatoes dataset. Our ensemble achieves improvements over individual models, with absolute accuracy gains of 1.6 percentage points on IMDB (93.1% vs.~91.5% for BERT) and 3.3 to 12.2 percentage points on Rotten Tomatoes. These results demonstrate the effectiveness of the proposed weighting strategy for sentiment classification.
Mohammed Mafaz Nadherssa
This paper introduces a computer science approach to large-scale skill estimation that unifies probabilistic modeling with algorithmic efficiency. We present a Bayesian rating framework that models skills, performances, and ranked evidence, deriving closed-form MAP updates and a pseudodiffusion mechanism for temporal skill evolution. The resulting algorithms exhibit monotonicity properties that support incentive-compatibility, robustness to outliers via heavy-tailed likelihoods, and parallelizable operation with a proven space complexity of O of n times the maximum of n and h times log log of 1 divided by epsilon per competition round, where n is the number of participants and h is the history length. The method achieves a time complexity of O of n divided by epsilon squared times log log of 1 divided by epsilon under practical approximations, including history truncation and opponent subsampling. Theoretical properties, including runtime bounds and robustness limits, are paired with empirical evaluations on multi-million-interaction datasets, demonstrating improved prediction accuracy and substantial speedups on large-scale datasets compared to widely used baselines.
Sheshukumar Vangala
This paper presents a structured algorithmic framework for automated physical design tuning in SQL-based relational databases. The approach centers on an incremental, anytime-capable optimization process that intelligently parses SQL workloads, identifies syntactically relevant and workload-significant table subsets and column groups, and iteratively refines candidate physical design structures including B+-tree indexes, materialized views, and partitioned indexes (conceptual framework support; see Section 4.1 for implementation status). Through a multi-phase methodology involving workload compression, candidate selection, index merging, and greedy enumeration, the system efficiently navigates the configuration space under storage and time constraints. A novel prioritization mechanism ensures early focus on high-impact queries while maintaining the ability to refine recommendations progressively. This SQL-native methodology is fully integrated with the query optimizer's what-if analysis interface (implemented as a prototype extension for PostgreSQL 14, using the HypoPG extension version 1.3.1 for hypothetical index evaluation) and is designed to support large-scale, dynamic workload environments with practical time-bounded tuning scenarios.
Sheshukumar Vangala
This paper presents an information technology-driven bibliometric framework for mapping the structural and temporal evolution of interdisciplinary intellectual linkage and apparent conceptual diffusion within the domain of social network analysis. Utilizing large-scale metadata from Web of Science, we construct multiple bibliometric networks representing citation, co-authorship, and keyword relationships. Through computational methods including fractional normalization, Search Path Count (SPC) edge-weighting, and island detection algorithms, we identify latent communities and bibliometric pathways that suggest patterns of intellectual association and citation-mediated influence between social sciences, physics, neuroscience, and behavioral ecology. These computational outputs represent citation-mediated influence patterns and co-occurrence structures, not direct observation of knowledge transmission. Our results highlight the role of digital libraries and algorithmic normalization in addressing terminological and data-quality challenges, alongside name disambiguation procedures and network pruning to mitigate citation boundary issues. This paper contributes to the domain of information technology by demonstrating scalable computational techniques for uncovering hidden intellectual structures and bibliometric evidence of knowledge flows in an increasingly interdisciplinary research landscape.
Rishabh Singh
This paper explores the application of machine learning to address the pervasive issue of flaky tests in software development within Java Virtual Machines (JVMs). Existing flaky-test detection approaches primarily focus on identifying whether a test is flaky but do not provide diagnostic information about why flakiness occurs. We present a framework that integrates statistical and machine learning techniques with dynamic taint analysis to automatically identify and tag candidate root causes of nondeterministic test failures. By tracking data flow using bytecode modifications, this approach facilitates automated debugging by providing evidence for candidate sources of nondeterminism. The framework is evaluated in terms of classification performance, diagnostic localization, and runtime overhead. The results indicate that the hybrid approach can effectively identify flaky tests and localize potential sources of nondeterminism in JVM-based software systems.
Akhil Veluru
The paper proposes an efficient semi-Lagrangian scheme on a CPU for simulating two-dimensional viscous incompressible fluids with GPU-assisted visualisations. We solve the Navier-Stokes equations on a quadtree adaptive grid where certain cells are subdivided if the velocity gradient, along any of the axes, exceeds a certain value. Generally speaking and in our tests, it results in a 66% reduction in active cells compared to a uniform grid with the same maximum resolution on average. During a test on an Intel Core i7-9700K processor with a static obstacle (Re=100), the implementation achieves 60 fps with an effective resolution of 256×256. (The GPU is used only for rendering through SFML). By using an adaptive grid, we achieved a speed-up of 2.7× over a uniform grid while maintaining vortex shedding and wake regions' visual effects. We demonstrate fluid interaction with static objects and achieve quantified boundary leakage below 1.2%. In addition, a sensitivity analysis of the method justifies a choice of five Gauss-Seidel iterations per time step. The technique is suitable for real-time interactive computing environments, games and high-res visuals.
Akhil Veluru
A fundamental limitation of classical rendering pipelines is that their discrete, non-differentiable structure makes them unsuitable for gradient-based parameter recovery. This paper presents a differentiable ray tracing framework that directly addresses this gap, enabling end-to-end optimization of object appearance, illumination, and viewpoint parameters from observed images. The framework is built around automatic differentiation, specifically the source-to-source AD mechanism provided by Zygote in Julia. In our experiments, AD-based gradient computation achieves a 60% reduction in wall-clock time compared to central finite differences for scenes with more than 50 optimized parameters, while reducing gradient approximation error by approximately two orders of magnitude. We validate the approach through controlled inverse rendering experiments. These results open practical pathways for applications in neural rendering, differentiable simulation, and broader inverse graphics research.
Muneebuddin Syed
This paper codifies a computer-science approach to graph layout by unifying constraint-driven tree positioning with force-based placement into reproducible, implementation-ready methods. It casts tree drawing as a linear optimization with level, separation, and centering requirements that implicitly ensure non-intersection, establishing planarity proofs and analyzing the asymptotic growth of constraints. For general graphs, it develops force-based layouts and Laplacian equilibrium methods with explicit convergence criteria, alongside studies of initialization sensitivity and resolution limits as graph size increases. Reference C++ implementations detail data structures, indexing passes, and solver choices leveraging open numerical libraries to realize these models efficiently in practice. Case studies on canonical families reveal symmetry preservation and degradation patterns, offering guidance on when to favor constraints versus forces in systems engineering and visualization pipelines.
Read the articles online or download individual PDFs from this issue.